Benchmarks & Deep Dives · Free
τ-bench (tau-bench)
τ-bench, written tau-bench and developed by Sierra Research, is an open-source benchmark that tests whether an AI agent can finish customer-service style tasks while talking to a simulated user, calling domain tools, and following a written policy. The original paper, published on arXiv in June 2024, covered retail and airline domains. A second paper, τ²-bench (June 2025), added a telecom domain in which both the agent and the simulated user can act on a shared environment, so the agent has to guide the user through steps as well as reason about the problem.
How scoring works. Each task starts from a known database state and a goal. The agent chats with an LLM-simulated user and may call tools such as booking changes or refunds. At the end, the benchmark compares the final database state with the annotated goal state and checks that required information was communicated. The path the agent took does not matter, only the outcome. The paper also introduced pass^k, a metric that asks whether an agent succeeds on all k repeated attempts of the same task. The authors reported that even strong function-calling agents of the time succeeded on fewer than half of tasks and were inconsistent across trials, which is why pass^k is a useful reliability signal for anyone planning to deploy an agent to customers.
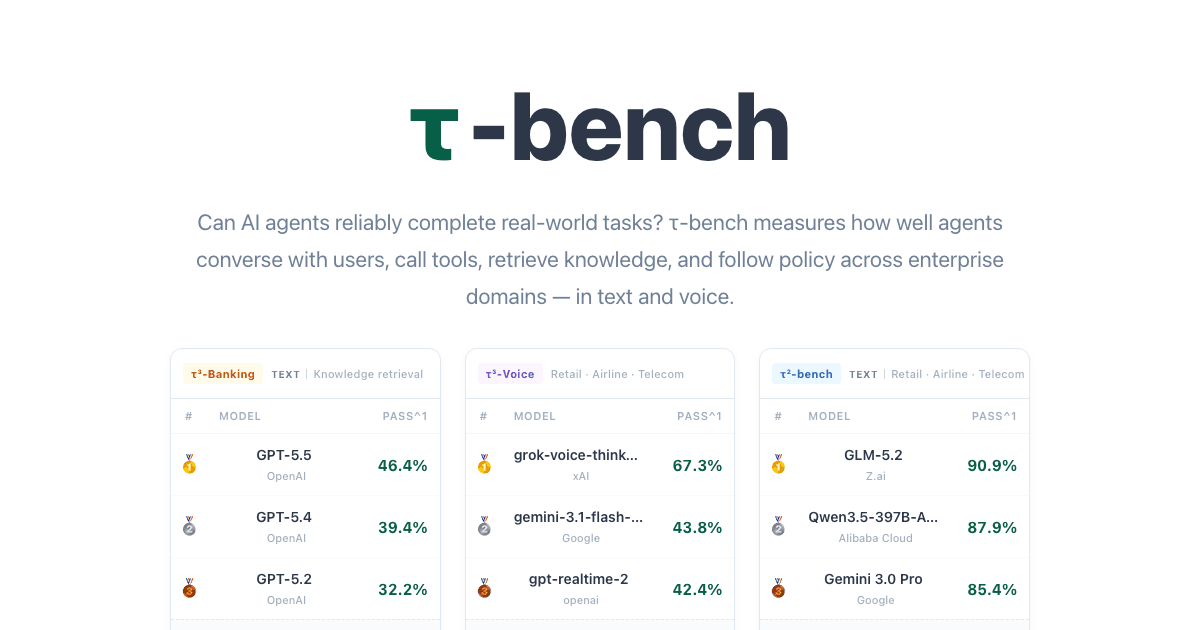
Versions matter. According to the project README, τ³-bench (version 1.0) added full-duplex voice evaluation, a banking_knowledge retrieval domain and more than 75 task fixes, and version 1.0.1 fixed grading on banking_knowledge, so earlier results on that domain are not comparable. Version 2.0 adds τ-i18n, the same airline, retail and telecom tasks in six languages in text and voice, plus an intake domain (called τ-Entity) with 200 tasks for capturing names and addresses exactly. The README says 2.0 scores are not comparable with the 1.x leaderboard, and the live leaderboard at taubench.com shows them on separate tabs.
Who it is for. Teams building support, booking or back-office agents that must obey rules, and anyone comparing models on policy-following and tool use rather than coding. It needs Python 3.12 or newer and the uv package manager, and you supply API keys for the agent model and the user simulator, so running it costs model usage but the software is free.
Limits to keep in mind. The user is simulated by another model, which adds noise, and the domains are small and specific. A high score shows reliable behaviour in these simulated workflows, not that an agent will handle your own policies. Alternatives include the Berkeley Function Calling Leaderboard for single and multi-turn tool calls, MCPMark for real MCP servers, and your own evals built with tools such as Promptfoo or Inspect. The official site is taubench.com and the code is at github.com/sierra-research/tau2-bench.